
Software teams often fall into one of two traps: they either build elaborate infrastructure for millions of users who may never arrive, or optimize entirely for today’s workload and discover that the system cannot handle its first serious traffic spike. Designing for scale from day one does not mean deploying every distributed-systems technology available. It means making early architectural choices that preserve the ability to grow without forcing an expensive rewrite later.
What “designing for scale” actually means at the start
Early scalability is primarily about avoiding architectural decisions that make future growth unnecessarily difficult, not about building infrastructure for hypothetical massive traffic.
A new application rarely needs the architecture of a global technology platform. A well-designed monolith running on a conventional relational database can support a surprisingly large workload, and it is usually easier to develop, test, deploy, and debug than a distributed collection of services.
The important question is whether the system can evolve.
If application logic is tightly coupled to individual servers, database access is uncontrolled, expensive operations block user requests, and every component depends directly on every other component, additional traffic can expose structural problems quickly. Adding more hardware may provide temporary relief without addressing the underlying limitations.
A scalable design instead creates clear boundaries and predictable behavior. Compute capacity should be relatively easy to add. Expensive work should be separable from interactive requests where appropriate. Data access should follow understandable patterns. Components should be observable enough that the team can identify bottlenecks before changing the architecture.
This approach preserves optionality. You do not need to implement sharding, multiple regions, Kubernetes, event streaming, or dozens of microservices on day one. You need an architecture that does not make those or other future changes unnecessarily painful if growth eventually requires them.
Core principles to bake in from the first architecture decision
The most valuable early scalability decisions are simple principles that reduce coupling, make capacity easier to add, and help engineers understand how the system behaves under load.
Five principles are particularly useful:
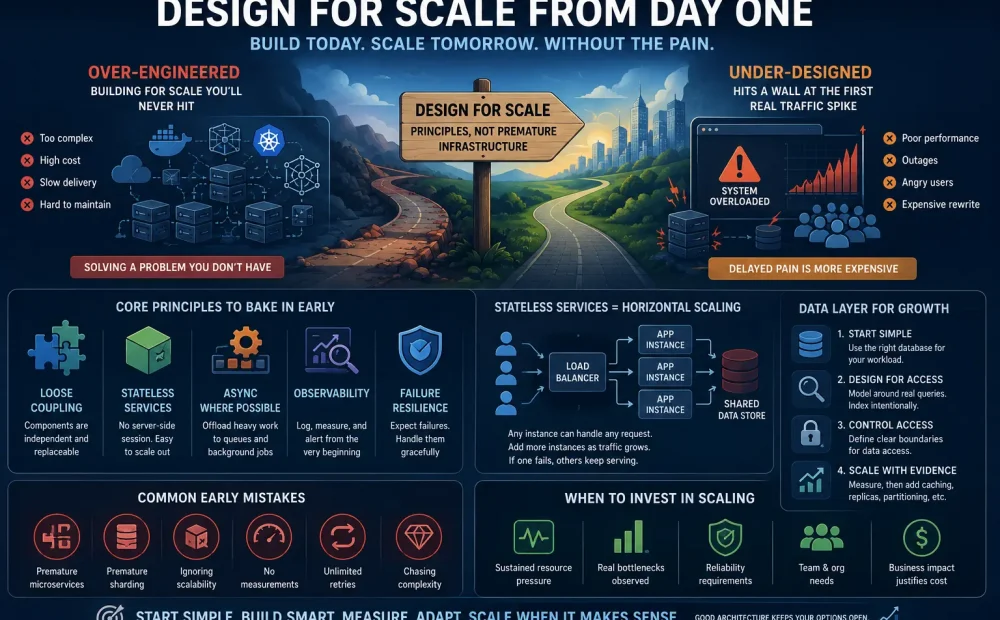
- Keep components loosely coupled. Define clear boundaries between major areas of the application so that one part can evolve without requiring changes throughout the entire codebase.
- Prefer stateless compute where practical. Avoid tying user sessions or essential application state to a particular application server. This makes it much easier to distribute requests across multiple instances.
- Separate synchronous and asynchronous work. Operations that do not need to finish before responding to the user can often move to background jobs or queues, reducing latency and protecting request-handling capacity.
- Design for observability. Implement meaningful logs, metrics, traces, health checks, and alerts early enough that engineers can determine where time and resources are actually being consumed.
- Assume dependencies will fail. External APIs, databases, networks, and internal services can become slow or unavailable. Timeouts, bounded retries, idempotency, and graceful failure behavior should be considered before outages force the issue.
These principles do not require a complicated architecture. In fact, many can be implemented inside a relatively simple application.
That distinction matters because scalability and architectural complexity are not the same thing. Complexity creates its own costs: more deployments, more failure modes, more monitoring, more networking, more operational knowledge, and more difficult debugging.
The objective is therefore not maximum sophistication. It is minimum complexity with sufficient room to grow.
Stateless services and why they matter for horizontal scaling
Stateless application services are easier to scale horizontally because any available instance can handle a request without depending on information stored only on one specific server.
Consider an application that stores a user’s session entirely in the memory of the server handling the first request. If another server receives the next request, it may not know who the user is or what happened previously.
One workaround is sticky sessions, which attempt to keep each user connected to the same server. This can work, but it introduces additional operational constraints and can complicate load distribution and failure recovery.
A more scalable pattern is to keep important state outside individual application instances. Session information might be stored in a shared data store, while persistent business data belongs in the database or another appropriate storage system.
Application instances can then become largely interchangeable.
If traffic increases, additional instances can be started and placed behind a load balancer. If an instance fails, requests can be routed elsewhere. If demand falls, capacity can be removed.
This is horizontal scaling: increasing capacity by adding more machines or instances rather than continually increasing the resources of one machine.
Statelessness should not be interpreted literally as “the application has no state.” Almost every useful application has state. The principle is that request-processing instances should avoid owning critical state that prevents another instance from taking over their work.
The same idea becomes valuable during deployments, autoscaling, recovery from failures, and eventually multi-region architectures.
How to structure your data layer for future growth
A scalable data layer begins with disciplined schemas, predictable access patterns, and measurement long before it requires exotic databases or sharding.
Teams can prepare for growth in four stages:
- Start with a database that matches the workload. For many transactional applications, a mature relational database is a strong default. Avoid selecting specialized distributed storage purely because the application might become large someday.
- Design schemas and indexes around real access patterns. Understand how data will be created, queried, updated, and deleted. Appropriate indexes and efficient queries often extend database capacity far more cheaply than major architectural changes.
- Control access to the data layer. Avoid allowing unrelated parts of the application to perform arbitrary queries without clear ownership. Defined data-access boundaries make caching, replication, partitioning, and future migrations easier.
- Scale based on measured bottlenecks. Introduce caching, read replicas, partitioning, specialized stores, or sharding when evidence shows that simpler optimizations are no longer sufficient.
Database scalability is often discussed as though sharding is inevitable. For many applications, it is not.
A team may achieve substantial growth through better queries, indexes, connection management, caching, larger database instances, read replicas, archiving strategies, and background processing before partitioning data across multiple database servers becomes necessary.
Data architecture should also account for migration. Schemas change as products evolve, and large tables make previously trivial migrations increasingly expensive. Teams should therefore avoid assuming that every schema change will always be instantaneous.
Caching deserves similar discipline. It can dramatically reduce repeated database work, but it also creates invalidation, consistency, and operational challenges. Cache what measurement shows is valuable rather than using caching as a default substitute for efficient data access.
Common scaling mistakes made early in a project
The most damaging early scaling mistakes usually come from optimizing for imagined future requirements or ignoring basic architectural discipline because current traffic is small.
Premature microservices are a common example. Breaking a small product into numerous independently deployed services can introduce network failures, distributed tracing, service discovery, version management, duplicated infrastructure, and complex local development before the team receives meaningful benefits from independent scaling.
Premature sharding creates a similar problem in the data layer. Distributing data across multiple database nodes can solve genuine capacity problems, but it complicates queries, transactions, migrations, backups, and operational recovery. Implementing it without evidence of need can make an early product slower to change.
At the opposite extreme, some teams ignore scalability entirely. They store critical files on local application servers, execute expensive reports during synchronous web requests, perform unbounded database queries, or depend on processes that can run only on one machine.
Another mistake is scaling without measurement. Slow performance may be blamed on the database when the real problem is an external API, inefficient application code, excessive serialization, poor indexing, or a badly configured connection pool.
Without observability, architectural changes become guesses.
Teams also frequently overlook failure amplification. An overloaded dependency becomes slow, callers retry aggressively, traffic increases further, and a partial problem becomes a broader outage. Timeouts, retry limits, backoff, rate limiting, and circuit-breaking patterns can help prevent these cascades when used appropriately.
Finally, engineers sometimes optimize for maximum theoretical throughput while ignoring maintainability. A system that can process enormous traffic but requires a highly specialized team to operate may be the wrong architecture for a company that has not yet established product-market fit.
When to actually invest in scaling infrastructure vs. wait
Scaling infrastructure should be introduced when measured demand, reliability requirements, or operational constraints justify its complexity—not simply because future growth is possible.
The clearest signal is sustained resource pressure. If application instances regularly approach capacity, horizontal scaling may be justified. If database CPU, storage throughput, connection limits, memory, or query latency repeatedly become bottlenecks despite reasonable optimization, the data architecture may need to evolve.
Traffic patterns matter as much as average traffic. A system may operate comfortably most of the day but struggle during product launches, scheduled jobs, marketing campaigns, or sudden bursts of activity. Load testing can reveal these limits before customers encounter them.
Reliability requirements can justify investment even before raw traffic does. A business-critical application may require redundancy, automated failover, stronger disaster recovery, or multi-region capabilities because the cost of downtime is high, not because the number of requests is extraordinary.
Team size can also drive architectural change. A monolith that scales technically may eventually become difficult organizationally if dozens of engineers need to deploy unrelated parts of the product independently. At that point, clearer service boundaries may solve a coordination problem rather than a traffic problem.
The key is to recognize scaling as a sequence of responses to evidence.
Begin with an architecture that is simple enough for the current team to understand and operate. Keep application instances replaceable where possible. Maintain clean boundaries. Move appropriate workloads to asynchronous processing. Treat the database carefully. Build observability into the system. Test important failure scenarios.
Then measure.
When a real bottleneck appears, address the simplest constraint first. Optimize a query before replacing the database. Add another application instance before redesigning the entire platform. Introduce a queue before creating a complex event-driven architecture. Separate a service when independent scaling or ownership produces a clear benefit.
Designing for scale from day one is ultimately not about predicting how large the system will become. It is about ensuring that if growth arrives, the architecture gives the team multiple reasonable ways to respond instead of forcing an emergency rewrite.